

MatrixNormalDistribution
MatrixNormalDistribution[Σrow,Σcol]
表示均值为零的矩阵正态分布,其行协方差矩阵为 Σrow,列协方差矩阵为 Σcol.
MatrixNormalDistribution[μ,Σrow,Σcol]
表示均值矩阵为 μ 的矩阵正态分布.
更多信息
- MatrixNormalDistribution 是 μ+
 .x.
 的分布,其中
 是一个矩阵,其独立同分布的矩阵元素服从 NormalDistribution[0,1] 分布.
- 服从矩阵正态分布的矩阵
 的概率密度和
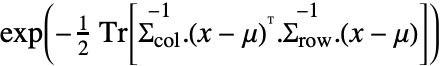 成正比.
- 对于任意正的实常数 c,MatrixNormalDistribution[μ,c Σrow,c-1 Σcol] 与 MatrixNormalDistribution[μ,Σrow,Σcol] 分布相同.
- 协方差矩阵 Σrow 和 Σcol 可以是大小分别为 {n,n} 和 {m,m} 的任意对称正定实数矩阵,而均值矩阵 μ 可以是大小为 {n,m} 的任意实数矩阵.
- MatrixNormalDistribution 可与如 MatrixPropertyDistribution、EstimatedDistribution 和 RandomVariate 这样的函数一起使用.
范例
打开所有单元 关闭所有单元基本范例 (2)
RandomVariate[MatrixNormalDistribution[{{3, 1, 1}, {1, 2, -1}, {1, -1, 4}}, {{1, -1 / 2}, {-1 / 2, 2}}]]Mean[MatrixNormalDistribution[{{1, 4}, {6, 8}, {10, 2}}, DiagonalMatrix[{2, 1, 3}], {{2, 1}, {1, 3}}]]//MatrixFormVariance[MatrixNormalDistribution[{{1, 4}, {6, 8}, {10, 2}}, DiagonalMatrix[{2, 1, 3}], {{2, 1}, {1, 3}}]]//MatrixForm范围 (7)
RandomVariate[MatrixNormalDistribution[{{1, 1 / 3}, {1 / 3, 1}}, IdentityMatrix[3]]]RandomVariate[MatrixNormalDistribution[{{1, 2, 3}, {4, 5, 6}}, {{1, 1 / 3}, {1 / 3, 1}}, IdentityMatrix[3]]]RandomVariate[MatrixNormalDistribution[{{1, 1 / 3}, {1 / 3, 1}}, IdentityMatrix[3]], 3]RandomVariate[MatrixNormalDistribution[{{1, 1 / 3}, {1 / 3, 1}}, IdentityMatrix[3]], WorkingPrecision -> 20]dist = MatrixNormalDistribution[{{3, 1}, {1, 2}}, ToeplitzMatrix[{4, 2, 1}]];sample = RandomVariate[dist, 10 ^ 3];edist = EstimatedDistribution[sample, MatrixNormalDistribution[Array[row, {2, 2}], Array[col, {3, 3}]]]比较两个分布的 LogLikelihood:
LogLikelihood[#, sample]& /@ {edist, dist}
NProbability[λmin > 0.1, λminMatrixPropertyDistribution[Min[Abs[Eigenvalues[m]]], mMatrixNormalDistribution[IdentityMatrix[10], IdentityMatrix[10]]]]dist = MatrixNormalDistribution[IdentityMatrix[2], DiagonalMatrix[{2, 1}]];PDF[dist, {{1., 2.}, {3, 4.}}]Plot3D[PDF[dist, DiagonalMatrix[{a, b}]], {a, -3, 3}, {b, -3, 3}]Skewness[MatrixNormalDistribution[{{2, 1}, {1, 3}}, IdentityMatrix[3]]]//MatrixFormKurtosis[MatrixNormalDistribution[{{2, 1}, {1, 3}}, IdentityMatrix[3]]]//MatrixForm应用 (2)
sigR = Covariance[ARProcess[{-0.95}, 1][Range[0, 100]]];
sigC = KroneckerProduct[IdentityMatrix[100, SparseArray], {{1, 1 / 2}, {1 / 2, 3}}];
vals = RandomVariate[MatrixNormalDistribution[sigR, sigC]];MatrixPlot[vals, PlotTheme -> "Minimal"]sigR = Covariance[ARProcess[{0.95}, 1][Range[0, 100]]];
sigC = KroneckerProduct[IdentityMatrix[100, SparseArray], {{1, 1 / 2}, {1 / 2, 3}}];
vals = RandomVariate[MatrixNormalDistribution[sigR, sigC]];MatrixPlot[vals, PlotTheme -> "Minimal"]sigR = Covariance[ARProcess[{a}, 1][Range[0, 100]]];
sigC = {{s11, s12}, {s12, s22}};rules = {a -> 1 / 2, s11 -> 1, s12 -> 1 / 2, s22 -> 3};dist = MatrixNormalDistribution[sigR, sigC] /. rules;vals = RandomVariate[dist, 10000];用抽样值构建 TemporalData:
td = TemporalData[vals, {0, Length[sigR] - 1, 1}, ValueDimensions -> 2];proc = ARProcess[{a IdentityMatrix[2]}, {{s11, s12}, {s12, s22}}];sol = FindProcessParameters[td, proc]sol[[All, 2]] - rules[[All, 2]]属性和关系 (6)
sigr = {{2, 1}, {1, 4}};
sigc = ToeplitzMatrix[{9, 3, 1}];
𝒟1 = MatrixNormalDistribution[sigr, sigc];c = 2;
𝒟2 = MatrixNormalDistribution[c * sigr, sigc / c];mat = RandomReal[{-10, 10}, {2, 3}]PDF[𝒟1, mat] == PDF[𝒟2, mat]MatrixTDistribution[Σrow,Σcol,ν] 是 MatrixNormalDistribution[Σ,Σcol] 的参数混合分布,其中  服从 InverseWishartMatrixDistribution[ν+n-1,Σrow]:
ν = 5;
n = 3;
Σr = IdentityMatrix[n];
Σc = IdentityMatrix[2];
invW = InverseWishartMatrixDistribution[ν + n - 1, Σr];
产生一个服从 MatrixNormalDistribution 和 InverseWishartMatrixDistribution 的参数混合分布的样本:
sampleSize = 10 ^ 3;
sigmas = RandomVariate[invW, 10 ^ 3];
sample = Table[RandomVariate[MatrixNormalDistribution[s, Σc]], {s, sigmas}];
把样本数据拟合到 MatrixTDistribution:
edist = EstimatedDistribution[sample, MatrixTDistribution[Array[s1, {3, 3}], Array[s2, {2, 2}], nu]]计算与相应的 MatrixTDistribution 相比所得的对数似然比统计量:
ratio = LogLikelihood[edist, sample] - LogLikelihood[MatrixTDistribution[Σr, Σc, ν], sample]对数似然比服从 ChiSquareDistribution,其中的参数等于自由度的数量:
dof = (Length[Σr] + 1) * Length[Σr] / 2 + (Length[Σc] + 1) * Length[Σc] / 2 + 1
pval = SurvivalFunction[ChiSquareDistribution[dof], 2ratio]mat = RandomVariate[MatrixNormalDistribution[IdentityMatrix[10 ^ 3, SparseArray], {{1, -1 / 2}, {-1 / 2, 2}}]];BaringhausHenzeTest[mat, MultinormalDistribution[{0, 0}, {{1, -1 / 2}, {-1 / 2, 2}}], "TestConclusion"]mat = RandomVariate[MatrixNormalDistribution[IdentityMatrix[10 ^ 3, SparseArray], {{1, -1 / 2}, {-1 / 2, 2}}]];BaringhausHenzeTest[mat, MultinormalDistribution[{0, 0}, {{1, -1 / 2}, {-1 / 2, 2}}], "TestConclusion"]data = RandomVariate[MatrixNormalDistribution[IdentityMatrix[3], {{1, -1 / 2}, {-1 / 2, 2}}], 10 ^ 5];Round[Table[Covariance[data[[All, i]], data[[All, j]]], {i, 3}, {j, 3}], 0.05]//MatrixFormRound[Table[Covariance[data[[All, All, i]], data[[All, All, j]]], {i, 2}, {j, 2}], 0.05]//MatrixForm通过把值为矩阵的随机变量组成的行结合在一起,矩阵正态分布可被视为多变量正态分布:
Subscript[Σ, r] = {{2, 1}, {1, 3}};
Subscript[Σ, c] = {{1, 1 / 2}, {1 / 2, 3}};mats = RandomVariate[MatrixNormalDistribution[Subscript[Σ, r], Subscript[Σ, c]], 5000];vecs = Flatten[mats, {{1}, {2, 3}}];

DistributionFitTest[vecs, MultinormalDistribution[{0, 0, 0, 0}, KroneckerProduct[Subscript[Σ, r], Subscript[Σ, c]]], {"TestDataTable", All}]可能存在的问题 (1)
可用倍增尺度常数定义矩阵正态分布. 估计参数可能与指定基本分布的参数不太一样:
sigr = ToeplitzMatrix[{4, 2, 1}];
sigc = DiagonalMatrix[{3, 1}];
dist = MatrixNormalDistribution[sigr, sigc];sample = RandomVariate[dist, 10 ^ 4];edist = EstimatedDistribution[sample, MatrixNormalDistribution[Array[s1, {3, 3}], Array[s2, {2, 2}]]];MatrixForm /@ {esigr = First[edist], sigr}MatrixForm /@ {esigc = edist[[2]], sigc}NumberForm[KroneckerProduct[sigr, sigc] - KroneckerProduct[esigr, esigc]//MatrixForm, 4]分布的 LogLikelihood 表明这是一个成功的估计:
LogLikelihood[#, sample]& /@ {dist, edist}文本
Wolfram Research (2015),MatrixNormalDistribution,Wolfram 语言函数,https://reference.wolfram.com/language/ref/MatrixNormalDistribution.html (更新于 2017 年).
CMS
Wolfram 语言. 2015. "MatrixNormalDistribution." Wolfram 语言与系统参考资料中心. Wolfram Research. 最新版本 2017. https://reference.wolfram.com/language/ref/MatrixNormalDistribution.html.
APA
Wolfram 语言. (2015). MatrixNormalDistribution. Wolfram 语言与系统参考资料中心. 追溯自 https://reference.wolfram.com/language/ref/MatrixNormalDistribution.html 年